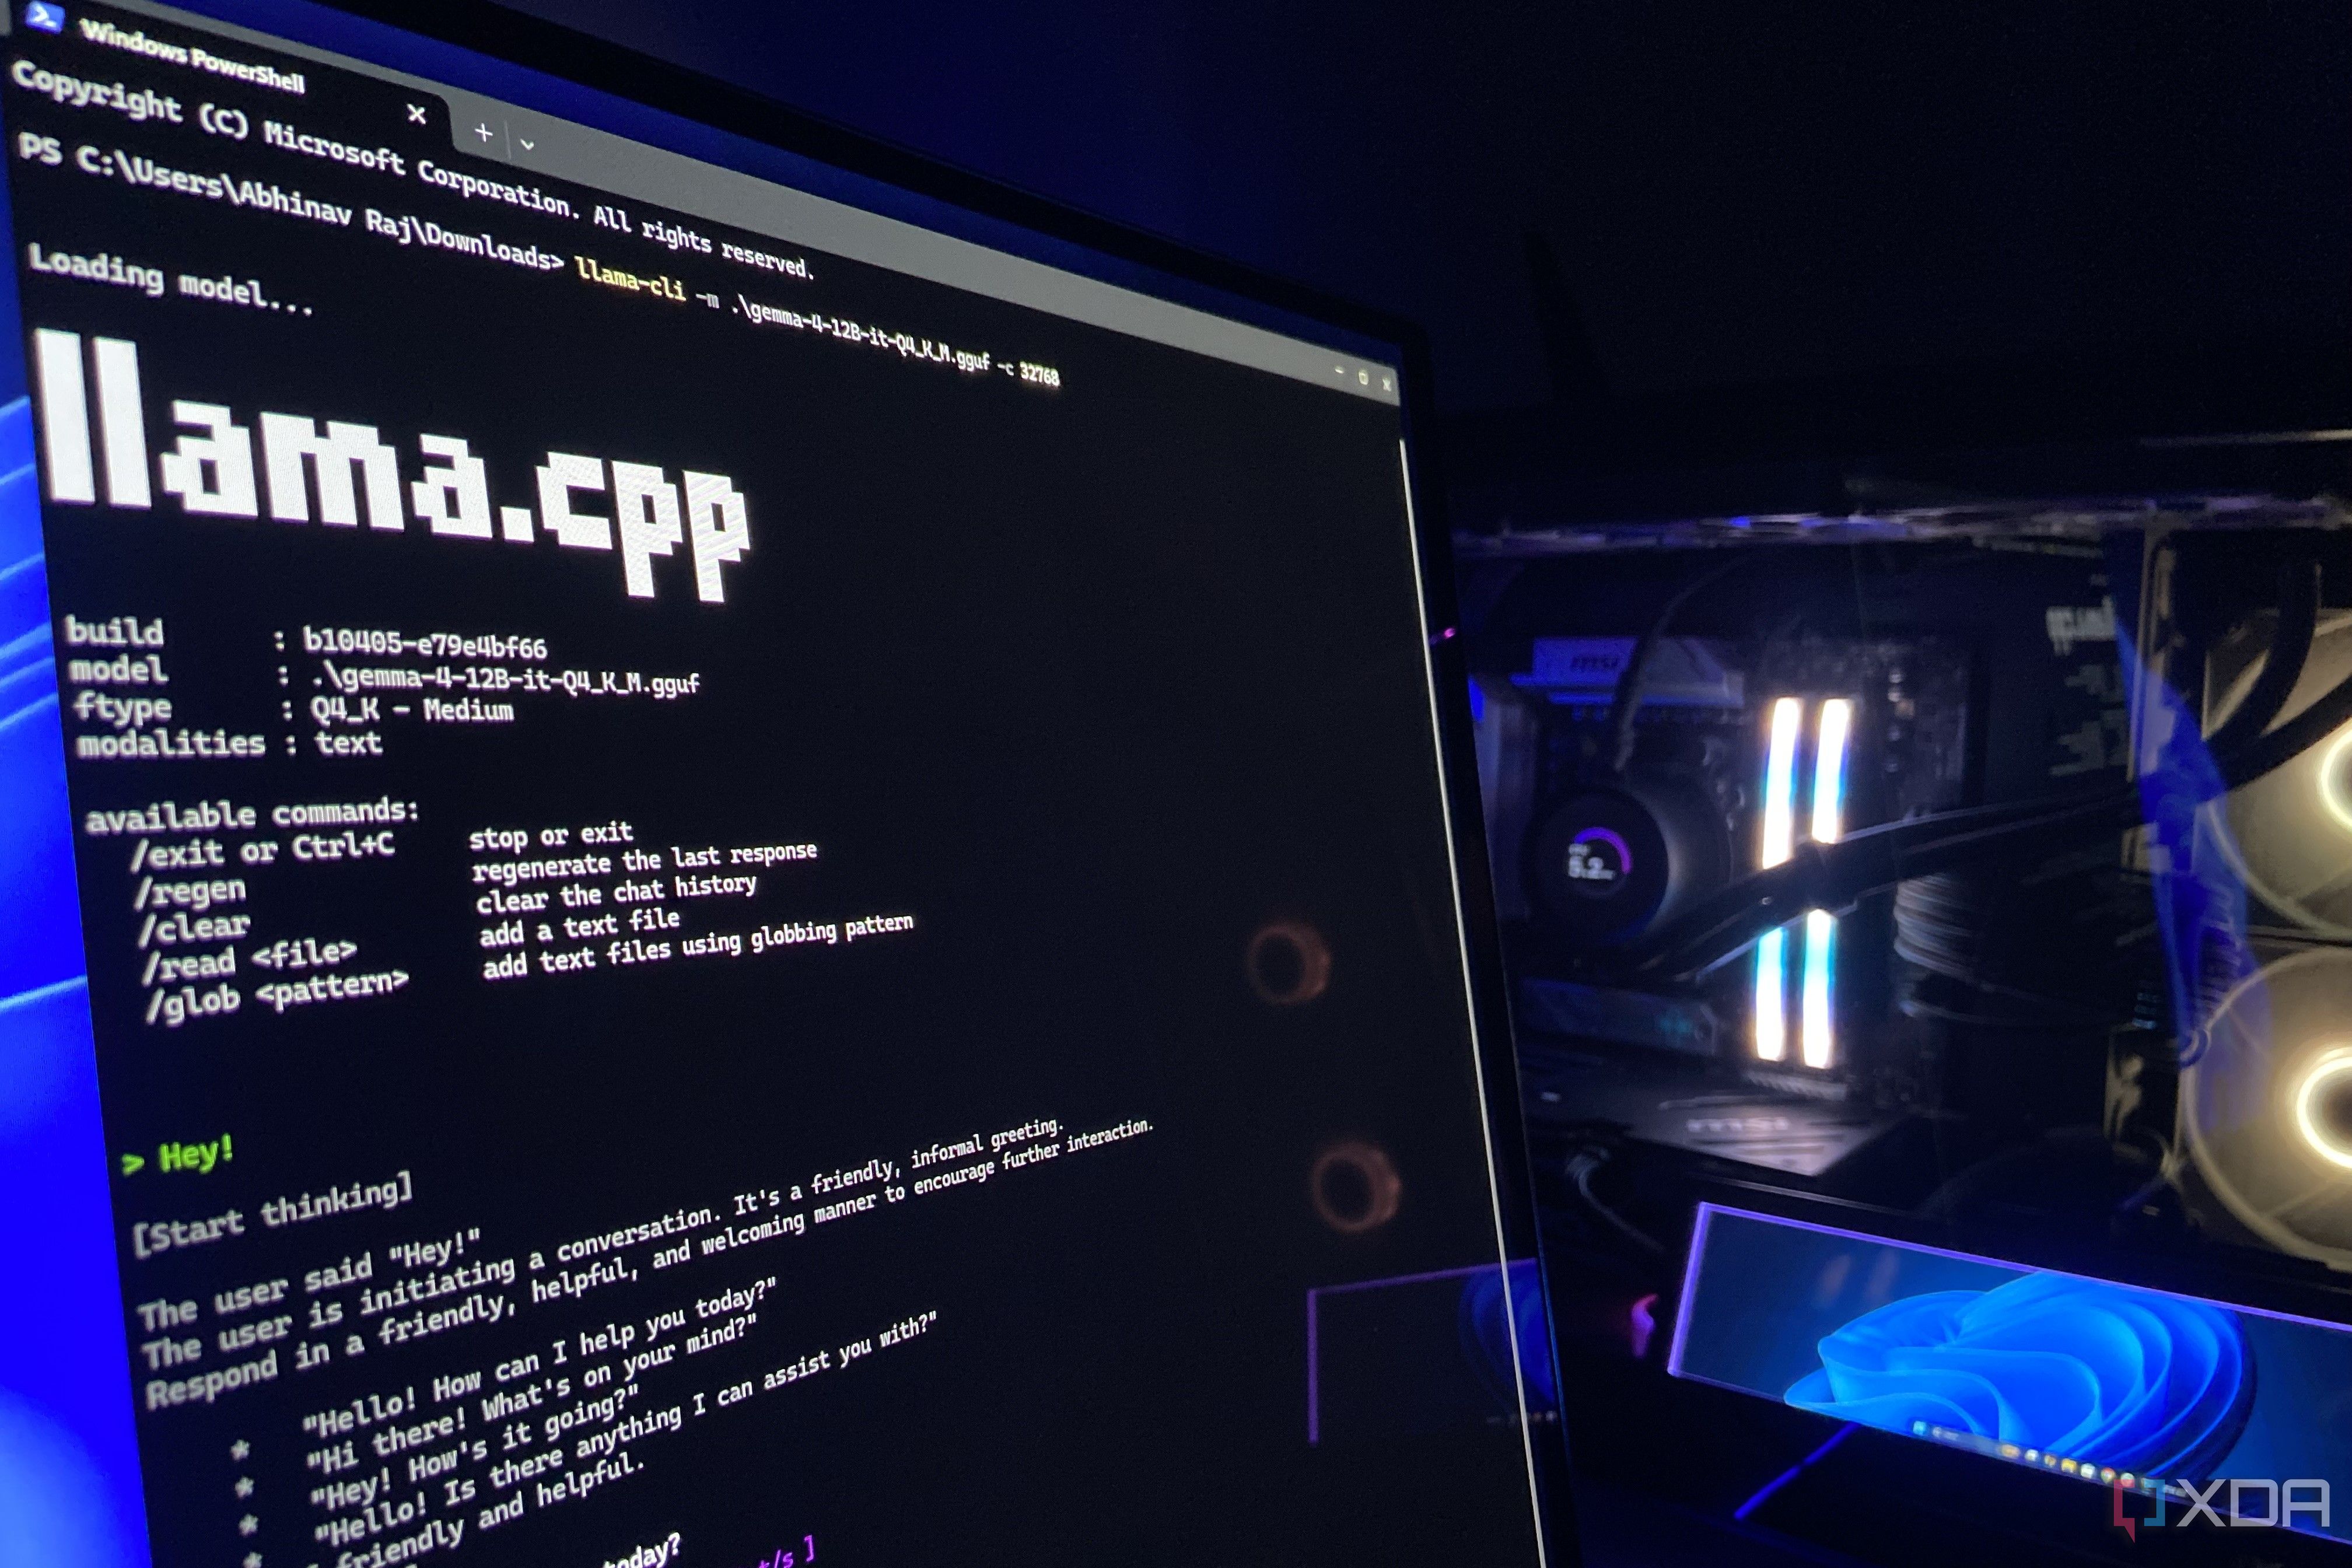
Running local artificial intelligence models has become increasingly popular among tech enthusiasts and developers looking to keep their data on-device. Tools like Ollama and llama.cpp serve as two of the most prominent frameworks for managing and executing these local language models.
In a recent hands-on account, a user documented their transition from Ollama to llama.cpp. While performance metrics and inference speeds are typically the main talking points when comparing machine learning runtimes, the decision to stick with llama.cpp ultimately came down to factors outside of pure execution speed.
The shift highlights the evolving priorities within the local AI community. Beyond quick responses, users increasingly value deeper configuration options, flexibility, and architectural control when running models on their personal setups.
For the full breakdown and hands-on comparison, check the original coverage on XDA Developers.